Canny sensitivity
[](https://www.python.org/)
Result
| Sr | Scene | textbook σ1.4 | best on **shapes** σ1.0 | best on **photos** σ2.0 | no smoothing σ0 |
|---|---|---|---|---|---|
| 1 | acacia and herd · edges 2% | 0.970 | **0.972** | 0.955 | 0.846 |
| 2 | alpine church · edges 14% | 0.507 | 0.468 | **0.531** | 0.391 |
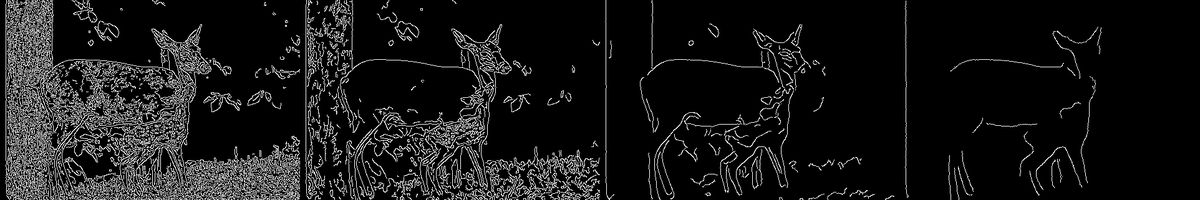
| 3 | deer and fawn · edges 21% | 0.623 | 0.486 | **0.719** | 0.307 |
| 4 | bears on a hillside · edges 37% | 0.238 | 0.146 | **0.310** | 0.135 |
The finding
Tuning on shapes costs 19%
On the generated scene, **12 of the configurations score a perfect F1 of 1.000**. A saturated benchmark has no power left to separate the things it is being asked to rank, so the choice among those twelve is arbitrary as far as it is concerned.
It is not arbitrary on photographs:
Identical on the benchmark, 19% apart on the real images. Pinned by test_tuning_on_shapes_costs_nineteen_percent_on_photographs and test_the_synthetic_scene_saturates.
The synthetic scene is not worthless — it is not decisive. Across the 18 settings both grids share, the correlation between synthetic F1 and photograph F is +0.751. It orders the settings roughly right and cannot pick between the good ones, which is exactly the failure mode of a benchmark everyone has already solved.
---
Figures
Elsewhere
Code and full results on GitHub (code private)
Every number is read from the file the run produced. github.com/hammasbuilds · kaggle.com/muhammadhammas13