Template matching
[](https://www.python.org/)
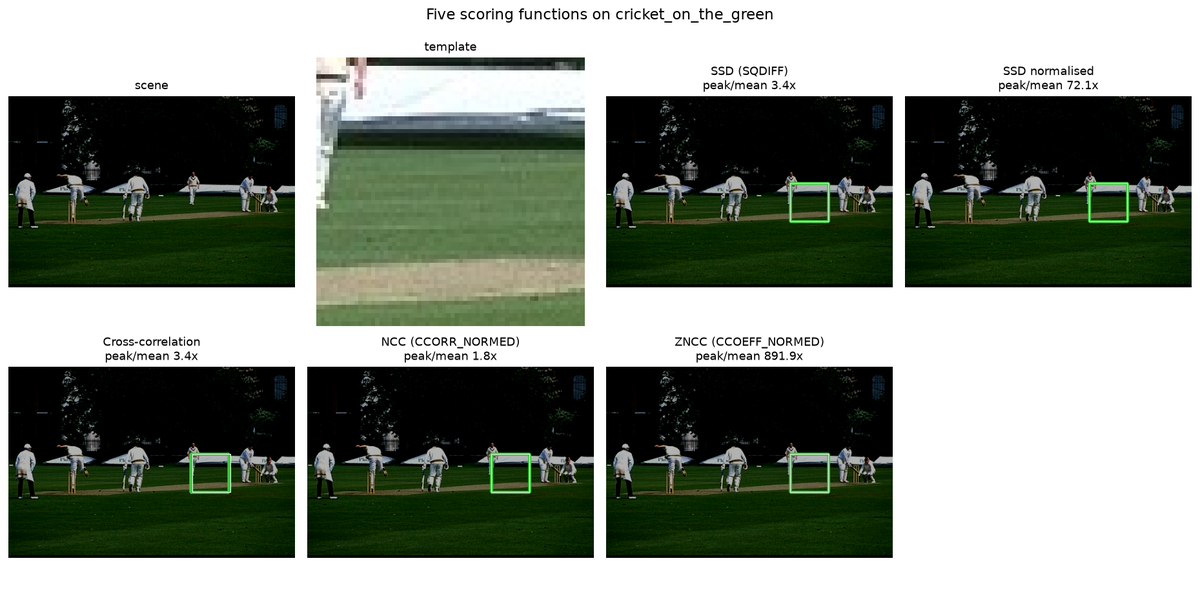
Result
| Sr | Scene | SSD | SSD normalised | Cross-correlation | NCC | **ZNCC** |
|---|---|---|---|---|---|---|
| 1 | hippo in green water · entropy 5.3 | 225 | 342 | 225 | 99 | **0** |
| 2 | elephants and grooms · entropy 7.4 | **0** | 111 | 111 | 305 | **0** |
| 3 | two at a railing · entropy 7.6 | 239 | 239 | 239 | **0** | **0** |
| 4 | monks at a noticeboard · entropy 7.9 | 154 | 144 | 144 | **0** | **0** |
The finding
The invariances, and the sign that reveals them
**At a tenth of the brightness NCC still localises every template and SSD normalised localises none.** Dividing by the standard deviation is exactly a scale invariance, and the sweep has to reach 10× before the claim is visible at all — at the usual gentle 0.9 every method still works.
> ZNCC holds 1.000 at every negative offset; NCC falls to 0.458. Subtracting > the mean is exactly an offset invariance, and NCC does not subtract the mean. > > It takes a negative offset to show it. Brightening clips at white and > destroys the structure for everyone — at +0.4 NCC and ZNCC both sit at 0.958 > and the difference between them is invisible. Darkening clips only in the > shadows, which leaves enough for a mean-subtracting method and not enough for > anything else. A sweep over positive offsets alone would have reported that > NCC and ZNCC are equivalent.
The algebra says the same thing with no image search involved. ZNCC of a patch against a·patch + b is 1.0 for any positive a and any b:
---
Figures
Elsewhere
Code and full results on GitHub (code private)
Every number is read from the file the run produced. github.com/hammasbuilds · kaggle.com/muhammadhammas13