Text to image
Generate an image from a text prompt.
Result
| model | tiny-SD (segmind/tiny-sd), UNet fine-tuned; VAE and text encoder frozen |
| data | Pokemon captions, 833 caption/image pairs at 512x512 |
The finding
Notes
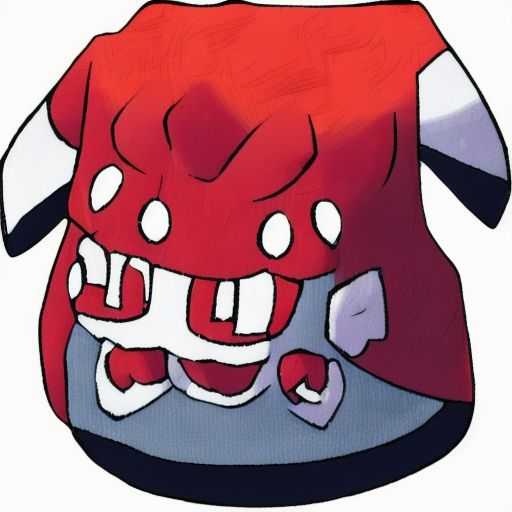
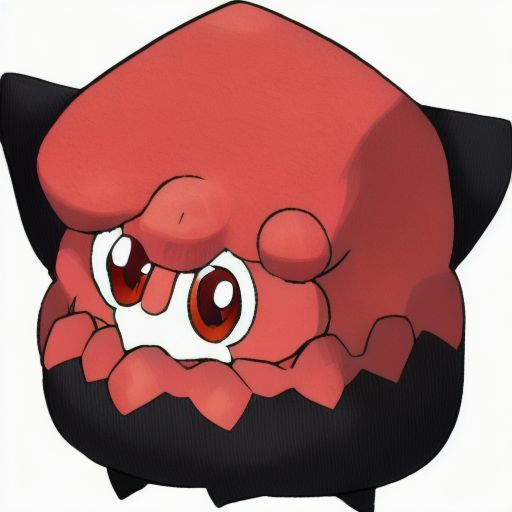
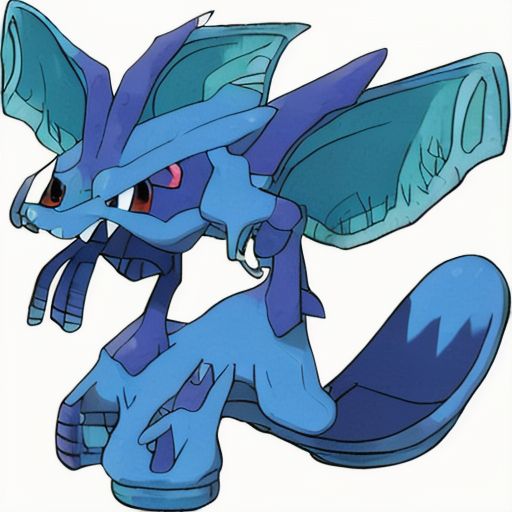
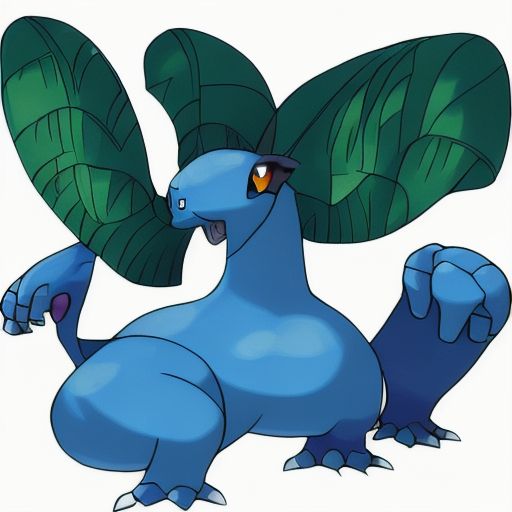
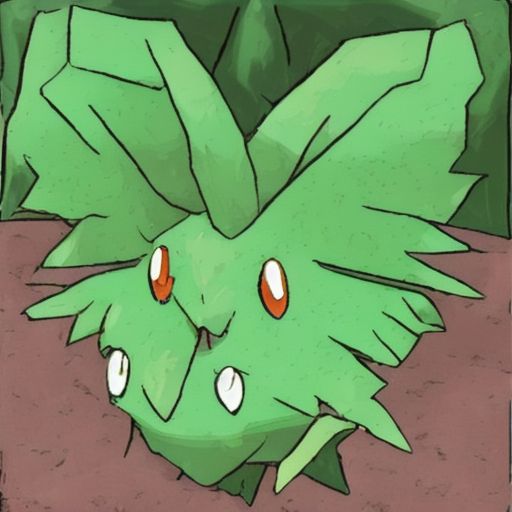
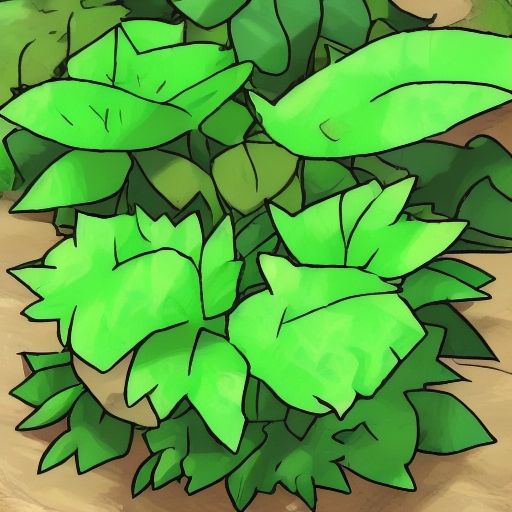
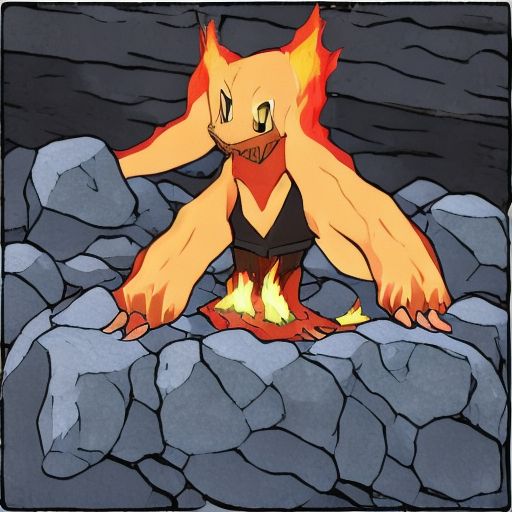
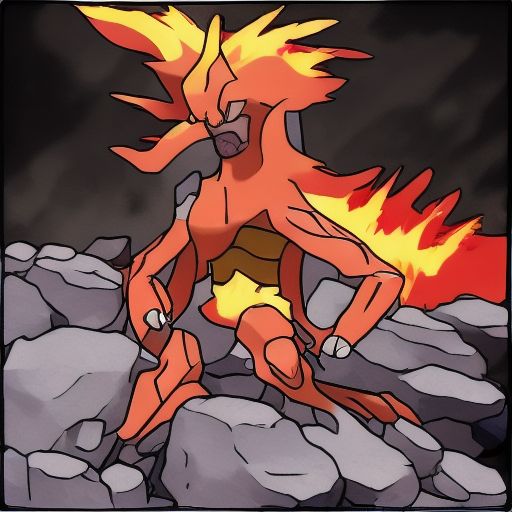
- 12,600 steps at batch 4, lr 1e-5, on 833 pairs. The run was stopped when two successive checks gained less than 0.2% - the remaining 2,400 steps of the 15,000 budget were not spent. - The best validation loss, 0.0513, was recorded at step 100; the loss then moved between 0.052 and 0.061 for the rest of the run. Diffusion training loss tracks sample quality loosely, so the samples are the thing to look at: samples/ holds the base model and the fine-tuned model on the same four prompts. - No held-out test split - this set is small enough that train and validation are the only two splits used.
Output
Same subject across the row; each column is the same stage in every project.
Elsewhere
Code and full results on GitHub
Every number is read from the file the run produced. github.com/hammasbuilds · kaggle.com/muhammadhammas13